

One QA team described reading 8,000 to 9,000 tickets per month by hand, and then moving to AI that runs quality assurance on 100% of tickets, freeing those ten reviewers to do other work entirely. A huge improvement in coverage.
That also quietly raises the stakes on a question most teams never actually settled: what is QA supposed to measure in such conditions?
You might have an agent that gets reaches a 100% score. Your feedback to them is that they fully met your expectations. But then that customer churns a week later.
So which one is telling you the truth?
When a human spot-checks ten tickets a week, a gap like that stays small and anecdotal. But when a model scores everything, a rubric pointed at the wrong target doesn’t mislead you occasionally. It misleads you at scale, on every ticket, with no one in the room to notice the customer was unhappy.
The immediate instinct is to fix it by bolting customer outcomes onto the score.
And yet, that instinct, I’d argue, gets it exactly backwards.
QA should measure the agent, not the outcome. The gap between a perfect score and a poor outcome isn’t a flaw. It’s actually an incredibly useful signal.
The Case for Keeping QA Focused on the Agent
The cleanest version of QA scores one thing: what the agent actually controls.
That means empathy, accuracy, tone, process adherence, and the quality of the decisions they made with the information in front of them. Did they understand the problem? Did they give a correct answer? And did they follow the steps they were supposed to? Did they treat the customer like a person?
These are all things an agent can be coached on, can improve at, and can be fairly held to. That’s the whole point of a QA score—it’s a coaching and development tool.
The moment you start baking ticket outcomes into that score, you break it.
- Outcomes are shaped by a long list of things the agent didn’t cause and can’t fix: a product bug, a pricing decision, a refund policy written by legal, an engineering backlog three sprints deep. Score the outcome, and you’re docking your best agent for a broken feature they flagged twice and got told to wait on.
- What’s worse is you’ve muddied the signal. A low QA score is supposed to tell you something specific: this agent needs coaching. Now you always have to consider that a low score means either the agent did something wrong or the product/policy/process did. You can’t read the number and figure out an action.
- Folding in KPIs like CSAT directly into your QA program will be unfair, too. Fin (formerly Intercom) notes that traditional CSAT surveys are incomplete and biased. They capture feedback from a small, self-selecting group that overrepresents the extremes. That doesn’t sound like a good foundation for your QA program.
This is the same trap that catches almost every support KPI.
Optimize any single metric in isolation, and you’ll eventually do it at the expense of everything around it. A QA score that tries to measure both the agent and the outcome ends up measuring neither one well.
The Case for Including Customer Outcomes in a QA Score
That was a convincing and tidy answer. It misses some things: QA used to be a person with a spreadsheet listening to a handful of calls a week.
Today it’s increasingly a model, scoring a far larger share of your tickets against a rubric that may itself have been AI-suggested.
If QA never touches outcomes at all, you can end up with a team scoring 95%+ across the board while customers quietly churn.
The scorecard becomes the definition of a vanity metric. It is beautifully calibrated instrument measuring craft in a vacuum. Looks nice and makes you feel good but doesn’t say anything meaningful about your customer experience.
The thing is that the purpose of support isn’t to “perform” quality. It’s there to get customers to a good place.
If your quality program can show you green dashboards while the people you’re meant to serve are unhappy, then your quality program is measuring the wrong thing or at least not enough of the right thing.
So there is a real tension:
- Score outcomes, and you punish agents for things outside their control.
- Ignore outcomes, and you risk a quality program that’s blind to whether your definition of “quality” actually impacts your customers.
Both sides are right about the other side’s weakness.
Customer Signals Should Shape the Rubric, Not the Score
The way through isn’t to split the difference and put a little bit of outcome into the score. That just gives you a slightly muddier number. The way through is to be precise about where customer signals belong.
Customer outcomes shouldn’t shape the score. They should shape the rubric.
CSAT, complaints, churn reasons, and CX signals are the best possible input for deciding what your QA rubric measures in the first place.
- If customers complain that answers are wrong, accuracy needs more weight.
- Maybe you see feedback from customers about having to repeat themselves more than once. That’s a signal that you need to focus on handoff and escalation.
This is also where AI quietly changes the work for the better.
- The same models scoring your tickets can mine thousands of conversations and surface the patterns a human sampling 2% would never see.
- But notice what AI doesn’t do: it doesn’t decide what counts as quality. A human still has to look at those patterns and choose what belongs on the scorecard.
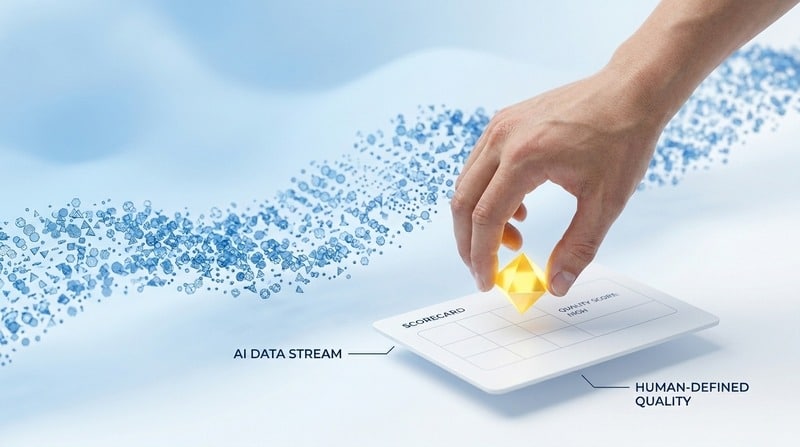
Machines can help you find those signals but your judgement decides what to do.
Once those questions are set, the thing you score is still the agent’s behavior against them.
This neutralizes the strongest argument against agent-focused QA. The vanity-metric problem (everyone scoring 95% while customers are unhappy) almost always means the rubric is measuring the wrong things. It’s measuring what’s easy to grade instead of what customers actually care about.
Feeding customer signals into rubric design fixes that directly, without negatively impacting agent performance and ticket outcome into one number you can’t interpret.
The Gap Between QA Scores and Customer Outcomes
An agent picks up a ticket.
They provide all the right information. They’re genuinely empathetic. Plus, they recognize the customer’s problem is real and that the fix sits outside their power, so they advocate for it internally. They keep the customer informed the whole way through.
And the outcome is still poor, because the feature the customer needed was a product change that isn’t coming.
What should that agent score?
That agent should be scored 100%. And they should be recognized for the advocacy work specifically, because that work is exactly what you want more of.
A high QA score sitting next to a bad customer outcome is not a contradiction you need to resolve. It’s a diagnosis. It’s your QA program telling you, with precision, that the problem in this ticket lives outside the support conversation.
That’s a valuable signal that you’re also responsible for transmitting further into your organization, as a support lead.
Drawing the Line in Practice
A few principles for building a QA program that holds this line.
- Score behavior and decisions, not results outside the agent’s control. The test for any rubric line is simple: could a great agent fail this through no fault of their own? If yes, it doesn’t belong in the QA score. It might belong in a different report, but not here.
- Make “did everything to improve the outcome” an agent behavior you score. Advocating internally, escalating to the right team, following through instead of forgetting, keeping the customer in the loop—these are all behaviors, all within the agent’s control, and all gradeable. Building them into the rubric means the agent who fights for a customer against a broken product gets rewarded for it, not penalized by association with the result.
- Track the gap deliberately, and route it to the right owner. “High QA score, low customer outcome” should be its own category that you actively watch. A pattern of perfect handling and poor outcomes on the same topic is one of the highest-signal things your support function can hand to the rest of the business.
- Measure outcomes too, but separately. The point isn’t to abandon customer outcomes. It’s just to stop forcing them into the QA score.
CSAT captures the customer’s read on the whole journey.
Even AI-driven measures like Fin’s CX Score report on separate reasons for negative scores, splitting between answer quality and product or service feedback.
In other words, even the outcome-measurement tools have concluded that “was the answer good?” and “was the product or policy the problem?” are different questions that need to be told apart.
Where the Upstream Problems Usually Live
When you start tracking the gap between QA scores and customer outcomes honestly, you’ll find a lot of “bad outcomes despite great agents” trace back to something surprisingly fixable.
Often it’s not a deep product flaw at all.
- It’s a knowledge gap, the answer existed, but wasn’t where the agent or customer could find it.
- It’s outdated help content that sent someone down the wrong path.
- Or it’s a process that forces agents to improvise because the right workflow was never documented.
These are upstream problems, but they’re not for engineering to solve. Knowledge and content problems are some of the most addressable issues a support team has.
That’s also why a healthy QA program and a healthy knowledge base reinforce each other.
A methodology like Knowledge-Centered Service turns those findings into a living knowledge base instead of a list of complaints, by making every agent responsible for capturing and improving knowledge as they go.
Closing the loop
This gap between score and outcome is exactly why we built ResolveLoop. It reads every closed ticket, not just the ones with a CSAT rating, and judges the whole interaction instead of only the agent. When a customer leaves unhappy despite great handling, ResolveLoop tells you whether the real cause was the product, a policy, a process, or a knowledge gap, so your high-QA, low-outcome tickets stop hiding in the data and reach the team that can actually fix them.
Take a look at ResolveLoop, our new product for support teams who want to know what really happened after a ticket closes.

Written by Nouran Smogluk
Nouran is a passionate people manager who believes that work should be a place where people grow, develop, and thrive. She writes for Supported Content and also blogs about a variety of topics, including remote work, leadership, and creating great customer experiences.


